
数据结构与算法 / 系统课时
设计搜索与推荐索引
设计搜索与推荐索引
当文档数量增长后,每次搜索都扫描全部内容会产生线性成本。倒排索引把“文档包含哪些词”反转为“每个词出现在哪些文档中”,查询可以直接定位候选集合。本课实现多关键词 AND 查询,并按热度与稳定键输出结果。
学习目标
- 使用倒排索引从关键词定位候选文档
- 通过集合交集实现多关键词 AND 查询
- 在匹配成立后应用热度和稳定排序规则
倒排结构、交集与排序
索引需要两类结构:documentId -> Document 保存文档详情,keyword -> Set<documentId> 保存关键词对应的 posting 集合。构建索引时,同一文档内的重复关键词应先去重,避免无意义的重复写入。
关键词还要经过统一规范化,例如去除首尾空白并按固定规则转小写。查询和建索引必须调用同一套规范化逻辑,否则看似相同的关键词可能落入不同的索引项。
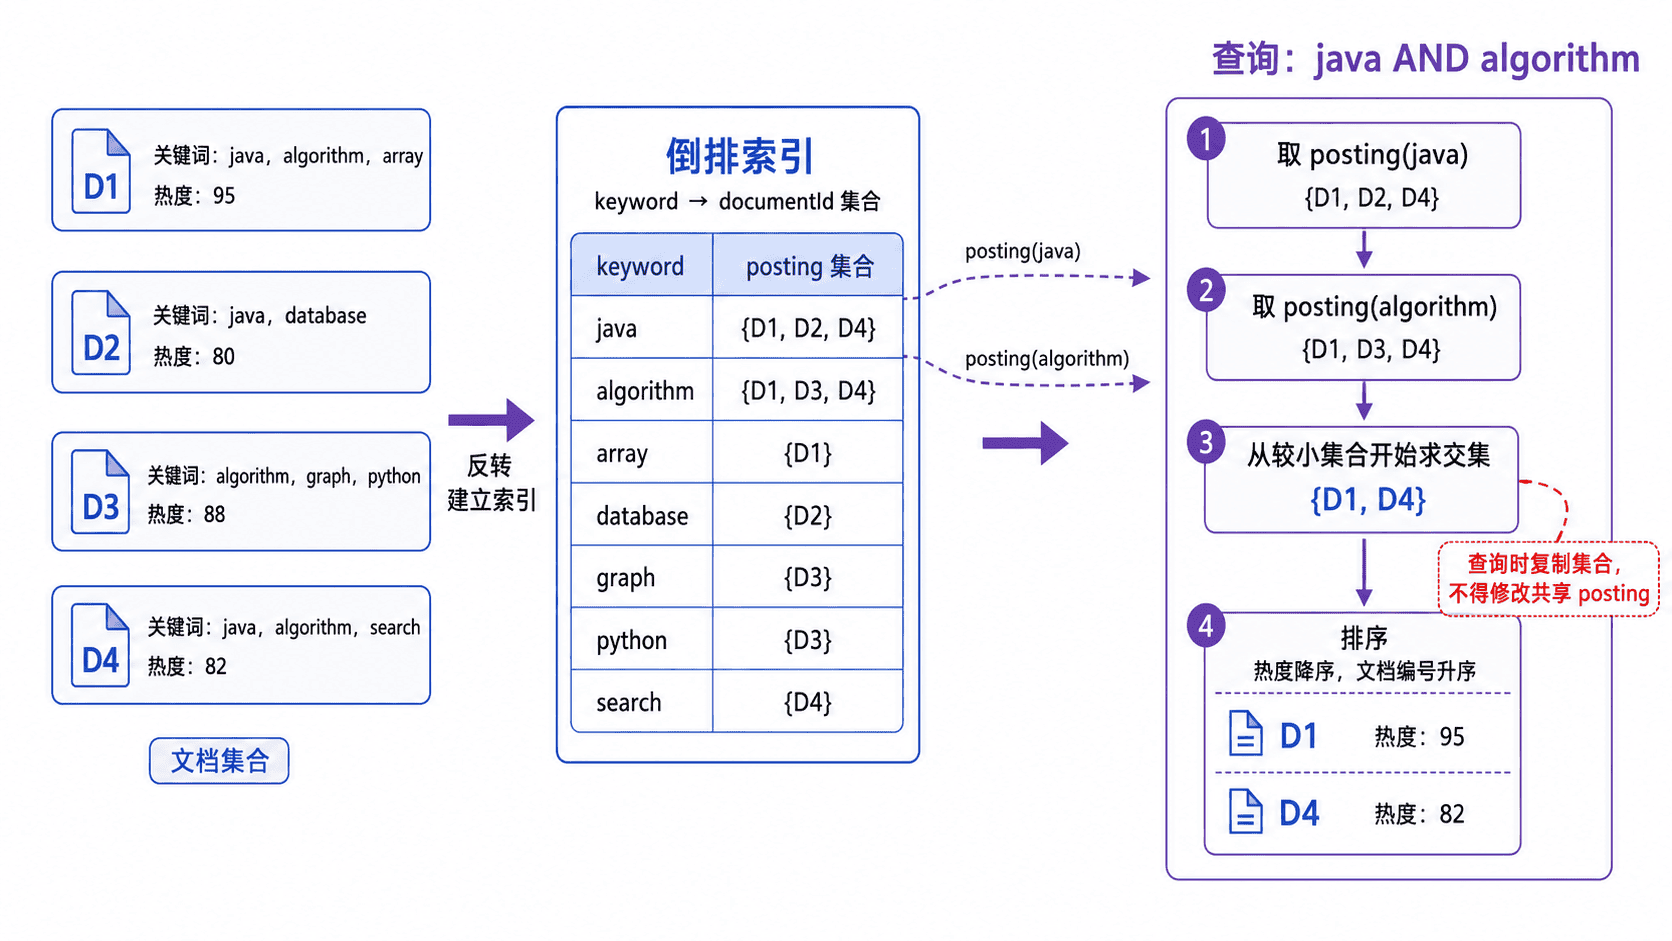
多个关键词必须同时出现时,需要对对应 posting 集合求交集。为减少中间结果,可以先按集合大小升序处理。查询时必须复制第一个集合,再执行 retainAll;如果直接修改索引内部集合,后续查询会永久丢失文档。
候选集合只解决“哪些文档匹配”。排序可以继续融合相关性、热度、时间或个性化信号。本课所有候选都命中全部关键词,因此按热度降序排列,并使用文档编号升序作为稳定次级键。
主示例:构建并查询索引
以下 Java 17 示例完成关键词规范化、索引构建、多关键词交集和稳定排序。
import java.util.ArrayList;
import java.util.Comparator;
import java.util.HashMap;
import java.util.HashSet;
import java.util.List;
import java.util.Locale;
import java.util.Map;
import java.util.Set;

public class SearchRecommendationIndexDemo {
    private record Document(
            int id, String title, int popularity, List<String> keywords) {
    }

    private static final class Index {
        private final Map<Integer, Document> documents = new HashMap<>();
        private final Map<String, Set<Integer>> inverted = new HashMap<>();

        Index(List<Document> source) {
            for (Document document : source) {
                if (documents.putIfAbsent(document.id(), document) != null) {
                    throw new IllegalArgumentException(
                            "重复文档编号: " + document.id());
                }

                Set<String> normalizedKeywords = new HashSet<>();
                for (String keyword : document.keywords()) {
                    normalizedKeywords.add(normalize(keyword));
                }
                for (String keyword : normalizedKeywords) {
                    inverted.computeIfAbsent(
                            keyword, key -> new HashSet<>())
                            .add(document.id());
                }
            }
        }

        List<Document> searchAnd(List<String> keywords) {
            if (keywords.isEmpty()) {
                return List.of();
            }

            Set<String> normalizedQueries = new HashSet<>();
            for (String keyword : keywords) {
                normalizedQueries.add(normalize(keyword));
            }

            List<Set<Integer>> postings = new ArrayList<>();
            for (String keyword : normalizedQueries) {
                Set<Integer> ids = inverted.get(keyword);
                if (ids == null) {
                    return List.of();
                }
                postings.add(ids);
            }
            postings.sort(Comparator.comparingInt(Set::size));

            // 复制候选集合,避免 retainAll 破坏共享索引。
            Set<Integer> candidates = new HashSet<>(postings.get(0));
            for (int i = 1; i < postings.size(); i++) {
                candidates.retainAll(postings.get(i));
                if (candidates.isEmpty()) {
                    return List.of();
                }
            }

            List<Document> result = new ArrayList<>();
            for (int id : candidates) {
                result.add(documents.get(id));
            }
            result.sort(
                    Comparator.comparingInt(Document::popularity)
                            .reversed()
                            .thenComparingInt(Document::id)
            );
            return List.copyOf(result);
        }

        private static String normalize(String keyword) {
            String normalized = keyword.trim().toLowerCase(Locale.ROOT);
            if (normalized.isEmpty()) {
                throw new IllegalArgumentException("关键词不能为空");
            }
            return normalized;
        }
    }

    public static void main(String[] args) {
        List<Document> documents = List.of(
                new Document(101, "Java 算法基础", 80,
                        List.of("Java", "algorithm")),
                new Document(102, "Spring 工程实践", 95,
                        List.of("java", "spring")),
                new Document(103, "数据结构", 90,
                        List.of("algorithm", "data")),
                new Document(104, "Java 算法练习", 88,
                        List.of("java", "algorithm", "practice"))
        );

        List<Document> result = new Index(documents)
                .searchAnd(List.of(" JAVA ", "algorithm"));

        System.out.println("查询关键词: [JAVA, algorithm]");
        for (Document document : result) {
            System.out.println(
                    document.id() + " | "
                            + document.title() + " | 热度 "
                            + document.popularity());
        }
    }
}
将代码保存为 SearchRecommendationIndexDemo.java,然后编译运行:
javac SearchRecommendationIndexDemo.java
java SearchRecommendationIndexDemo
预期输出:
查询关键词: [JAVA, algorithm]
104 | Java 算法练习 | 热度 88
101 | Java 算法基础 | 热度 80
索引维护与边界
文档新增、修改和删除都要同步更新正向数据与全部 posting。修改关键词时,不能只加入新词,还要移除旧词;某个 posting 变为空集合后应及时清理。若主数据和索引分开存储,还需要通过事务、版本号或异步重建机制处理一致性。
倒排索引缩小了候选范围,但不等于完整推荐系统。真正的推荐排序还可能使用用户画像、时间衰减和去重规则;这些信号应在满足检索条件后融合,不能让高热度但不相关的文档进入结果。