
Go / 系统课时
用 pprof 定位 CPU 与内存热点
用 pprof 定位 CPU 与内存热点
当程序“变慢”或内存持续上涨时,先采样再优化比猜测可靠。本课用一个可运行程序同时生成 CPU 与 heap profile,再用 go tool pprof 的 top、peek 和不同内存采样维度判断到底是算得太多、分配太频繁,还是对象被长期持有。
学习目标
- 生成并读取 CPU profile 与 heap profile。
- 用
flat、cum和调用关系定位 CPU 热点。 - 区分高分配量
alloc_space与高存活量inuse_space对应的问题。
先采集可重复的 CPU 与 heap profile
下面示例使用标准库 runtime/pprof,不依赖第三方包。CPU 采样持续约 2 秒;随后制造约 125 MiB 的短命分配,并保留约 8 MiB 对象,再主动执行一次 GC 后写出 heap profile。这样同一份数据能同时展示“频繁分配”和“长期持有”两类问题。
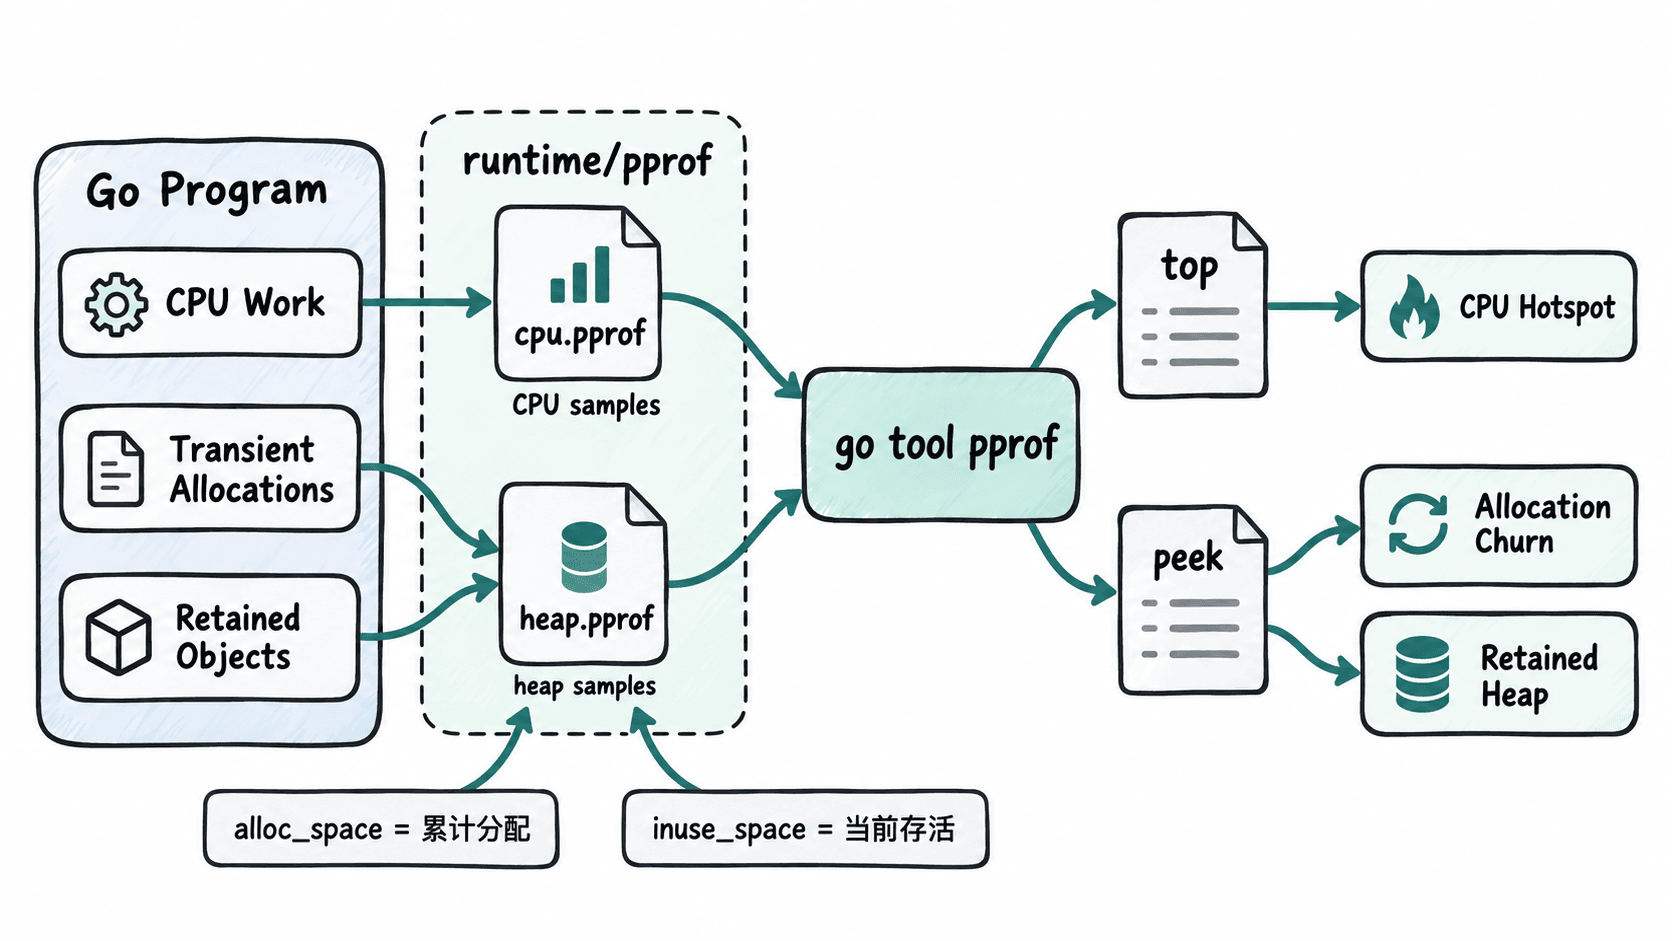
完整示例,保存为 main.go:
package main

import (
	"fmt"
	"log"
	"os"
	"runtime"
	"runtime/pprof"
	"time"
)

var cpuSink uint64
var retained [][]byte
var last []byte // 强制短命缓冲区逃逸到堆,便于观察累计分配。

func burnCPU(d time.Duration) uint64 {
	// 用持续时间控制采样窗口,避免不同机器固定循环次数差异过大。
	deadline := time.Now().Add(d)
	var x uint64 = 1
	for time.Now().Before(deadline) {
		for i := 0; i < 200_000; i++ {
			x = x*1664525 + 1013904223
		}
	}
	return x
}

func transientAlloc(rounds int) {
	for i := 0; i < rounds; i++ {
		b := make([]byte, 64<<10)
		b[0] = byte(i)
		last = b
	}
	last = nil
}

func retainMemory(chunks int) {
	retained = make([][]byte, 0, chunks)
	for i := 0; i < chunks; i++ {
		b := make([]byte, 256<<10)
		b[0] = 1
		retained = append(retained, b)
	}
}

func main() {
	cpuFile, err := os.Create("cpu.pprof")
	if err != nil {
		log.Fatal(err)
	}
	if err := pprof.StartCPUProfile(cpuFile); err != nil {
		log.Fatal(err)
	}

	cpuSink = burnCPU(2 * time.Second)
	// StopCPUProfile 会等待 profile 数据写完,再关闭文件。
	pprof.StopCPUProfile()
	if err := cpuFile.Close(); err != nil {
		log.Fatal(err)
	}

	transientAlloc(2000)
	retainMemory(32)
	// 先 GC,让默认的 inuse_space 更聚焦仍被引用的对象。
	runtime.GC()

	heapFile, err := os.Create("heap.pprof")
	if err != nil {
		log.Fatal(err)
	}
	if err := pprof.WriteHeapProfile(heapFile); err != nil {
		log.Fatal(err)
	}
	if err := heapFile.Close(); err != nil {
		log.Fatal(err)
	}

	fmt.Println("created cpu.pprof and heap.pprof; retained=8 MiB")
}
预期结果:代码使用标准库即可编译;运行后当前目录会出现 cpu.pprof 与 heap.pprof。执行:
go mod init example.com/pprof-demo
go run .
预期输出:
go: creating new go.mod: module example.com/pprof-demo
created cpu.pprof and heap.pprof; retained=8 MiB
如果目录已经有 go.mod,不要重复执行 go mod init,只运行 go run .。
用 top 找出最贵的函数
CPU profile 统计程序实际消耗 CPU 的采样位置。先看 top,重点比较 flat 与 cum:flat 是函数自身消耗,cum 是函数连同它调用的下游函数的累计消耗。
go tool pprof -top cpu.pprof预期输出的时间与百分比会随机器变化,但应看到 main.burnCPU 位于前列:
File: pprof-demo
Type: cpu
Duration: <DURATION>, Total samples = <SAMPLES>
      flat  flat%   sum%        cum   cum%
<CPU_TIME> <PERCENT> ... <CPU_TIME> <PERCENT>  main.burnCPU
如果某函数 flat 很高,说明热点就在它自身;如果 flat 很低但 cum 很高,通常要继续向它调用的子函数追踪,而不是直接改这个入口函数。
用调用关系确认热点来自哪里
top 能告诉你“谁贵”,peek 则适合快速看某个函数的调用者与被调用关系。对 CPU 热点执行:
go tool pprof -peek=main.burnCPU cpu.pprof预期输出会显示 main.main 调用 main.burnCPU,采样数值仍会因机器而异:
<CPU_TIME> <PERCENT> | main.main
<CPU_TIME> <PERCENT> | main.burnCPU
在真实服务里,如果 handler 的 cum 很高而 flat 很低,再对它的下游函数逐个 peek,通常比只盯着路由函数更快找到真正消耗 CPU 的序列化、压缩、正则或计算逻辑。
用 heap 区分频繁分配与长期持有
heap profile 同时能回答两个不同问题:inuse_space 看采样时仍存活的内存,适合查缓存过大、引用未释放等问题;alloc_space 看程序运行以来累计分配量,适合查临时对象太多、GC 压力过高。
echo "=== live ==="
go tool pprof -top -inuse_space heap.pprof
echo "=== allocated ==="
go tool pprof -top -alloc_space heap.pprof
预期结果中,具体采样值可能略有偏差,但归因应接近下面的结构:
=== live ===
Type: inuse_space
<ABOUT_8_MIB> ... main.retainMemory

=== allocated ===
Type: alloc_space
<ABOUT_125_MIB> ... main.transientAlloc
<ABOUT_8_MIB> ... main.retainMemory这两个视图不能互相替代:alloc_space 高而 inuse_space 低,说明对象大多已经回收,优先减少临时分配;inuse_space 持续高,才应该重点检查缓存上限、全局引用、goroutine 生命周期和集合是否只增不减。heap profile 是采样数据,因此不要把显示值当作逐字节精确计数。
把 profile 结论变成可验证的修复
修复前先记录同一负载下的基线。CPU 热点优先处理高 flat 函数;高 cum、低 flat 的入口继续向下追。分配热点先减少循环内 make、重复转换和短命缓冲区;长期持有则检查对象是否仍被 map、slice、缓存或后台 goroutine 引用。
修改后在相同输入、相近运行时长下重新采样,再比较 top。不要只凭一次 profile 宣布优化成功,因为请求量、数据规模和 GC 时机会直接改变样本分布。